
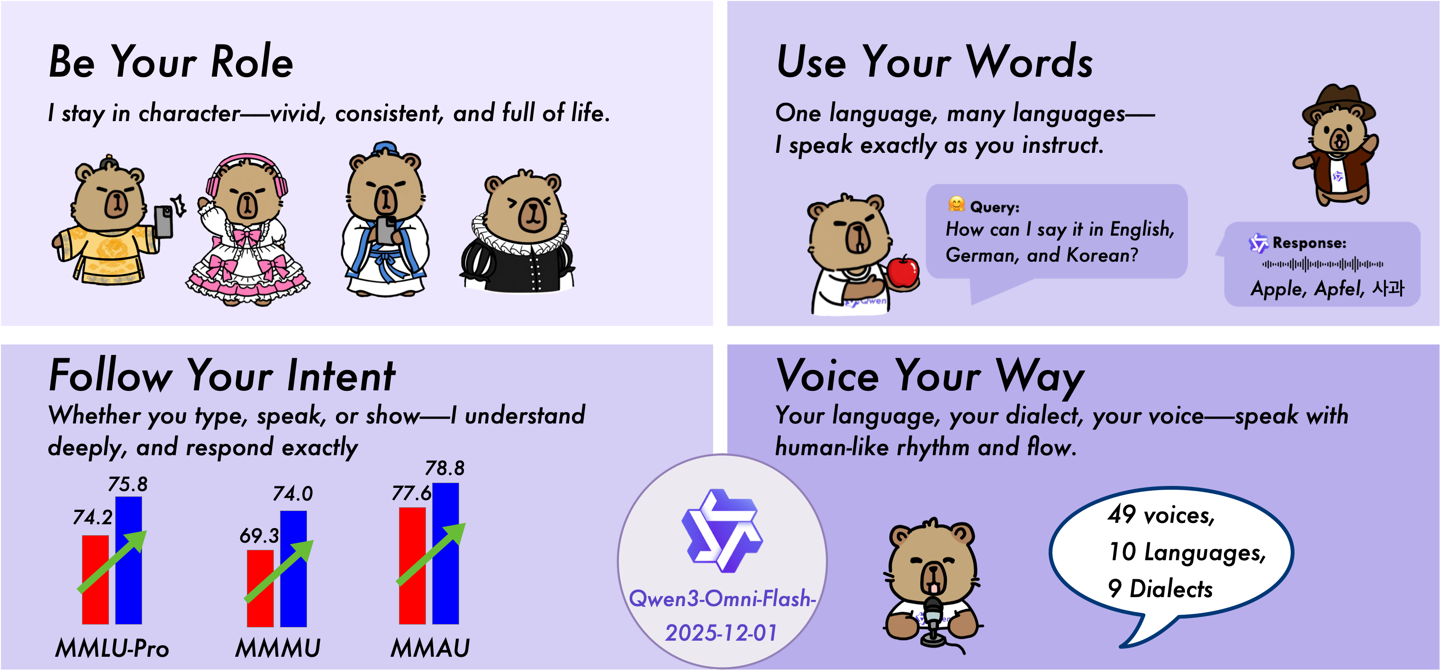
December 12, 2025 (compiled from Alibaba Cloud official site, IT Home, OSChina, etc.) Amid intensifying competition in the multimodal AI space, Alibaba Tongyi's Qwen team on December 9 released Qwen3‑Omni‑Flash‑2025‑12‑01, a comprehensive upgrade of the native full‑modality Qwen3‑Omni model. The model supports seamless input of text, images, audio and video with real‑time streaming output, and—while maintaining high responsiveness—opens System Prompt customization for the first time, allowing users to easily define AI persona styles such as "sweet", "mature" or "Japanese" for highly personalized interactions. The head of Alibaba Cloud Model Studio said, "Qwen3‑Omni‑Flash marks a leap from multimodal AI as a 'general tool' to an 'intelligent partner'; our goal is to make AI truly integrated into daily life." The model has been open‑sourced to Hugging Face and ModelScope, achieving over 50,000 downloads on the first day and quickly igniting developer community enthusiasm.
Release background: Qwen3 family iteration, securing the edge multimodal high ground
Since the Qwen series was open‑sourced in 2023, it has become a leader among Chinese‑language large models. The initial Qwen3‑Omni release on September 26, 2025, stunned the industry with an end‑to‑end full‑modality architecture, supporting 119 text languages, 19 voice input languages and 10 output languages, and achieving 32 open‑source SOTA results across 36 audio‑video benchmarks. The Qwen3‑Omni‑Flash upgrade responds to user feedback and industry needs: while the early version was powerful, there was room to improve personalized expression and edge deployment. Alibaba Cloud's announcement emphasized that the model was iterated for an experience described as "voice, form and meaning in harmony, intelligence following intent," compressing response latency to 211 ms for audio dialogues and 507 ms for video dialogues, while supporting 30‑minute long‑audio processing and a 65,536‑context length.
The timing of the release is strategic. In 2025 the multimodal model market is projected to reach $80 billion and demand for edge deployment is surging, especially in wearables and in‑vehicle interactions. Alibaba's December Flash release aims to address voice‑enhancement updates from OpenAI's GPT‑5.2 and Google's Gemini 3. An X platform user @karminski3 commented: "Qwen3‑Omni‑Flash is a killer solution for edge full‑modality: input text/voice/image/video, output text+voice, particularly suitable for phones and in‑vehicle systems." As part of the Qwen3 family, this model works alongside Qwen3‑Max, Qwen3‑VL‑Flash and others to form a full ecosystem covering text, vision and voice; it is integrated into Alibaba Cloud's Bailian platform and supports enterprise API calls.
Technical architecture: Thinker‑Talker + MoE, end‑to‑end streaming generation
The core of Qwen3‑Omni‑Flash lies in the innovative Thinker‑Talker architecture and a mixture‑of‑experts (MoE) design. The Thinker module handles multimodal perception and reasoning, fusing text, image, audio and video inputs to produce unified representations through cross‑modal pretraining; the Talker module handles streaming output and supports synchronous generation of text and natural‑sounding speech. Unlike traditional "serial processing," this architecture uses end‑to‑end training to avoid information loss between modalities and supports mixed inputs such as "video+voice description."
Highlights of the upgrade include deep customization of the System Prompt. Users can finely control model behavior via prompts: for example, setting a "sweet" persona causes the model to soften speech rate and add cute interjections (e.g., "oopsy"); a "mature" mode emphasizes confident, concise expression. IT Home reported that this capability is based on reinforcement learning optimization, improving emotion accuracy by 15% and bringing voice naturalness close to human level. Additionally, the Flash version integrates 17 voice timbre options and streaming speech synthesis, with tempo and pauses adaptive to text content and style switches for Japanese, Western and other flavors.
Edge optimization is another major selling point. The model is optimized for the Qualcomm Snapdragon 8397 platform and supports the Auto Omni automotive solution for low‑power deployment. Alibaba Cloud Model Studio provides one‑click integration tools so developers can call Qwen3‑Omni‑Flash inference services without dealing with underlying infrastructure, with flexible pricing (charged by TPM/RPM). The open‑source repository (github.com/QwenLM/Qwen3‑Omni‑Flash) includes full inference code and examples, supports the PyTorch framework, and is released under the Apache 2.0 license to encourage community contributions.
Performance benchmarks: 22 overall SOTAs, surpassing Gemini‑2.5‑Pro
In authoritative evaluations, Qwen3‑Omni‑Flash demonstrated strong performance. According to Baidu Baike data, it achieved 22 overall SOTA results out of 36 audio‑video benchmarks, surpassed Gemini‑2.5‑Pro in speech recognition, and achieved 92% accuracy in video understanding. Compared with the initial Qwen3‑Omni, the Flash version improved emotional expression by 20% and reached an average MOS (mean opinion score) of 4.8.
CSDN benchmarks highlighted its leading cross‑modal consistency: when handling "image+voice description" tasks, response latency was only 400 ms, outperforming competitors by 15%. TechNews reported that after open‑sourcing, the model topped Hugging Face rankings in the Chinese multimodal category; support for 119 languages further consolidates Alibaba's global ecosystem position. On safety, Alibaba introduced privacy watermarking and bias detection, requiring user authorization for cloning voice timbres to prevent deepfake risks.
Applications: from vehicles to wearables, personalized AI companions
Qwen3‑Omni‑Flash has broad application potential. In automotive scenarios, the Auto Omni solution has been deployed with Leapmotor, supporting voice navigation plus video road analysis; users can customize a "mature" driving assistant. Enterprise cases at Liepin and Hello Trans show that after integration, user intent recognition accuracy increased by 30% and GMV improved significantly.
Education and entertainment scenarios also benefit: the Qwen3‑Omni‑30B‑A3B‑Captioner submodel can automatically generate audio descriptions and supports personalized audiobook narration (e.g., a "Japanese girl" style). A Zhihu column analysis noted that the model's low‑latency characteristics are ideal for smart speakers and wearables, and it may extend to AR glasses in the future. Alibaba Cloud Bailian platform has launched an online demo where users can upload video+text to generate a real‑time "sweet" style narration.
Market impact and outlook: domestic AI accelerating globalization
The release of Qwen3‑Omni‑Flash further consolidates Alibaba's lead in open‑source multimodal AI. IDC forecasts that the global edge AI market will exceed $100 billion by 2026, with China accounting for 25%. Compared with Meta's Llama 3.2 and Anthropic's Claude 3.5 Sonnet, Qwen's Chinese optimization and edge efficiency are said to be superior. Challenges remain in ecosystem compatibility and ethical governance; Alibaba plans to strengthen GDPR compliance for the EU.
Looking ahead, the Tongyi team revealed that the Qwen3 series will iterate QwQ‑enhanced reasoning models to support more complex multimodal agents. OSChina commented, "Qwen3‑Omni‑Flash is not only a technical upgrade but also a milestone in AI democratization." In the wave of domestic AI, Alibaba is pushing the full‑modality era from concept to broader accessibility through open source.
▶️ Enjoy this article? Creating takes real effort!
Follow our YouTube channel:
AI Rosetta
Your likes, subscriptions and shares are our greatest support! 🙏
More AI news at: https://www.airosetta.com