
On September 10, 2026, DeepSeek officially released DeepSeek V4.1 Flash. This is the smallest‑size member of its new model‑architecture series and features native multimodal visual understanding. The company explicitly states that the new architecture is designed to raise capability ceilings, speed up inference, increase throughput, and scale smoothly to larger parameter models. The API has been launched in parallel under the model name deepseek‑flash.
Details: architectural innovations and performance
DeepSeek V4.1 Flash is a 552B‑parameter mixture‑of‑experts (MoE) model that adopts a brand‑new Causal‑Encoder‑Decoder (CED) design. The input and output sides are asymmetric: the activated parameters on the input side are about 8B, and about 16B on the output side, which significantly reduces inference cost compared with known models of similar total scale. The model natively accepts combined image‑and‑text inputs and generates text autoregressively, without requiring an external vision module.
Other key technical features include:
- Support for a maximum context length of 1,000,000 tokens;
- Pretraining on roughly 45T multimodal tokens, with sparse attention trained at sequence lengths of 64K and subsequently extended to 1M;
- Post‑training follows an SFT → Reinforcement Learning → Offline Policy Distillation (OPD) pipeline;
- Major KV cache compression: compared with the previous generation, HBM requirements drop to about 1/4 and SSD requirements to about 1/8; the overall cache size has been reduced by multiple orders of magnitude relative to the initial model, substantially lowering storage and cost burdens for long‑context and multi‑turn agent scenarios.
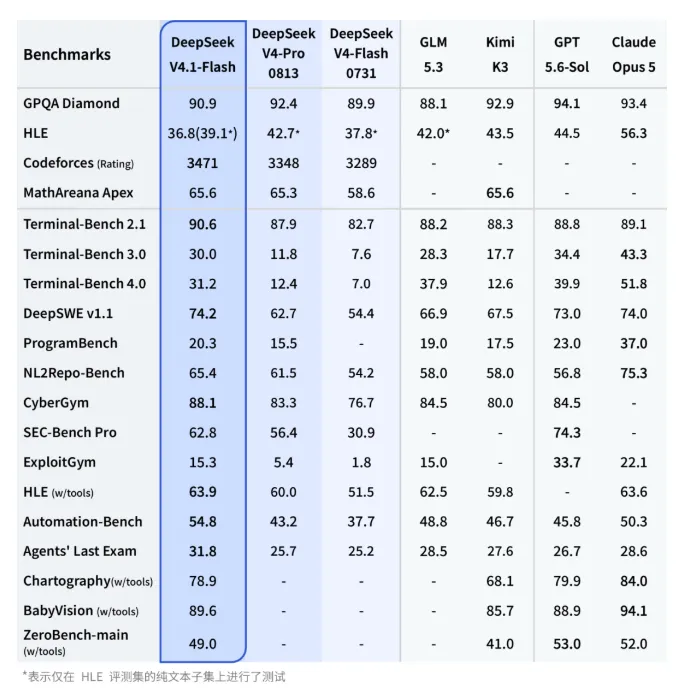
The company published selected benchmark results showing strong performance for V4.1 Flash on multiple tasks, for example GPQA Diamond 90.9, Terminal‑Bench 2.1 90.6, DeepSWE v1.1 74.2, CyberGym 88.1, and claims that it comprehensively surpasses the previous flagship model DeepSeek V4 Pro (across performance, cost, speed and total runtime).
API and product strategy adjustments
After V4.1 Flash launched, the former V4 Flash and V4 Flash Vision Exp were taken offline; related legacy model names are temporarily routed to the new model. The company plans to route all V4 Pro requests to V4.1 Flash starting at 12:00 (Beijing Time) on September 14, 2026, and charge at the Flash unit price until V4.1 Pro is officially launched. This means that, during the transition period, chat and API traffic will be heavily concentrated on V4.1 Flash.
Pricing was lowered in parallel and continues to use peak‑valley time‑based billing: during off‑peak periods, prices for input cache hits, input cache misses and outputs are respectively CNY 0.02, CNY 1, and CNY 4 per million tokens; peak‑period prices are twice the off‑peak rates. The new prices took effect from 12:00 on September 10. Tencent products and some partners have already integrated the new model.
Potential impacts: reshaping cost‑effectiveness and signaling architectural evolution
1. Impact on developers and users
Lower activated parameters, drastically reduced KV cache requirements, and lower pricing make long‑context, multi‑turn agent and multimodal workloads materially cheaper to run. Delivering performance that reportedly exceeds the prior Pro model at a Flash positioning and price further strengthens DeepSeek’s presence in the “high cost‑effectiveness” segment, potentially attracting more small‑to‑medium teams and high‑frequency usage scenarios.
2. Impact on the model product line
Consolidating fast, expert and vision modes and temporarily routing Pro traffic to Flash indicates the company is accelerating convergence of its product matrix and simplifying user choices. It also suggests the new architecture is highly scalable, and larger V4.1‑series models may follow quickly.
3. Impact on competitive landscape
Against continuous iteration from OpenAI, Anthropic and other domestic vendors, DeepSeek’s combination of the CED structure, aggressive KV compression and native multimodality reiterates that architectural innovation can drive both efficiency and capability improvements. If real‑world experience and benchmarks align, this could further compress mid‑to‑high‑end API pricing and motivate more vendors to focus on asymmetric activation, cache compression and scalable architectures.
4. Technical significance
The Causal‑Encoder‑Decoder design and large KV compression are important attempts to address cost bottlenecks in long‑context and agent scenarios. The design of lower activation on the input side and relatively higher activation on the output side reflects a "compute‑on‑demand during inference" approach. Native multimodality integrated from pretraining also helps consistency for vision‑language tasks.
5. Points to watch
The company’s benchmarks and the claim of "fully surpassing V4 Pro" still require third‑party reproduction and verification in real business settings. The routing strategy may lead to experience changes for some heavy Pro users during the transition; the actual delivery timeline and any open‑source plans for larger models will determine the long‑term influence of the new architecture.
Conclusion
DeepSeek V4.1 Flash’s release marks an important milestone in DeepSeek’s 2026 model iterations. By combining a "small‑size new architecture + native multimodality + significant efficiency gains," it aims to strike a better balance among capability, speed and cost, and the company is rapidly pushing it to market through product measures (price reduction, traffic consolidation).
If subsequent usage data and larger‑model validations confirm the architecture’s scalability, this series could become an important domestic technical path for long‑context, agent and multimodal scenarios. For the industry, it is another reminder that beyond parameter‑count competitions, structural innovation and inference efficiency are becoming decisive factors for real‑world competitiveness.
▶️ Enjoy this article? Content creation is hard!
Follow our YouTube channel:
AI Rosetta
Your likes, subscriptions and shares are our greatest support! 🙏
More AI news at:
https://www.airosetta.com