
On New Year’s Day 2026 the DeepSeek team released a preprint titled "mHC: Manifold‑Constrained Hyper‑Connections" that has attracted wide attention in the AI community. The paper, by Xie Zhenda, Wei Yixuan, Cao Huanqi and DeepSeek founder Liang Wenfeng (arXiv:2512.24880), proposes a new architecture called mHC designed to address the instability of traditional Hyper‑Connections (HC) in large language model (LLM) training while preserving their performance benefits. As a follow‑up innovation to DeepSeek‑V3, mHC restores the core property of residual connections—the identity mapping—by imposing a mathematical "manifold constraint" and adds engineering optimizations to enable more efficient training. The concept is not mystical: it is a careful optimization of how information flows through neural networks. This article explains mHC step by step in accessible terms, with metaphors and the key mathematical details to help readers follow the full logic from problem diagnosis to solution.
Why do neural networks need "residual connections"?
To understand mHC, start with a basic neural‑network problem. Deep models such as Transformers are like very tall buildings: each layer processes information and passes it to the next. If information is only passed layer by layer, it can be lost or distorted—the well‑known problems of gradient vanishing or explosion. In 2015 Kaiming He and colleagues introduced residual connections, which act like a direct elevator or highway next to the stairs: each layer’s output is not just F(x) but x + F(x). Here x is the original signal that "skips" the layer, ensuring smoother information flow.
Why does this help? It implements an identity mapping: if the layer’s update F(x) is near zero, the output is approximately x and the signal is neither amplified nor diminished. Mathematically, this preserves signal mean and keeps norms bounded, allowing gradients to propagate stably during backpropagation. Wrapping each Transformer block (Attention + FFN) with residuals is what lets networks stack hundreds or thousands of layers.
HC’s innovation and pain point: a multi‑lane highway without guardrails
Residuals are stable but single‑stream—like a one‑lane highway with limited capacity. In 2024 ByteDance proposed Hyper‑Connections (HC): expanding the single residual path into multiple parallel channels (expansion rate n, typically 4–8), allowing information to cross‑mix among these "lanes." Think of it as a multi‑lane highway where the main lane is x but extra lanes split off, are processed, then merged back, and lanes can change via fully connected or random matrices.
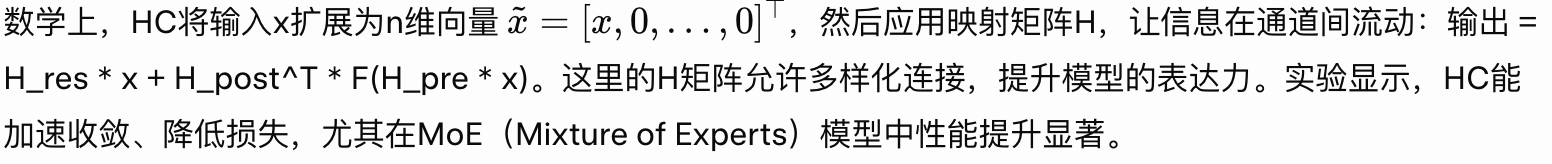
But this introduced a big problem: unrestricted lane changing causes frequent "traffic accidents." Signals can be amplified without bound (the paper reports amplification of over 3,000x), training becomes unstable—loss spikes, gradient norms explode, and memory access overhead grows. At trillion‑parameter scale this can crash training. The root cause is that HC breaks the residual identity mapping: an unconstrained H matrix can arbitrarily scale signals, like a highway with no speed limits or guardrails.
mHC core idea: add guardrails to the multi‑lane design
DeepSeek’s mHC adds "guardrails" to HC by constraining H to a special mathematical space—the Birkhoff polytope of doubly stochastic matrices. Informally, a doubly stochastic matrix has non‑negative entries and each row and column sums to 1, enforcing conservation of total mass.
Why does this help? It makes mixing a convex combination: the output is a weighted average of input features with total mass preserved, so signals are neither amplified nor shrunk. Metaphorically: imagine water flowing in multiple lanes; after mixing, each bucket still contains unit volume. Mathematically this guarantees:
- Signal mean conservation: E[y] = E[x], so the mean is unchanged.
- Spectral norm ≤ 1: the matrix’s largest singular value is ≤ 1, preventing exponential signal amplification.
- Closure under composition: the product of multiple such H matrices remains doubly stochastic, giving end‑to‑end stability.
How is this constraint realized? By using the Sinkhorn–Knopp algorithm: starting from an initial matrix (denoted \tilde{H}), alternately normalize rows and columns (divide by sums) for a number of iterations (the paper reports ~20) to project into the doubly stochastic space. The operators T_r and T_c denote row and column normalization respectively. The Sinkhorn method dates back to 1967 and is simple and efficient, adding only modest compute overhead.
In mHC layer flow, the input is first expanded to n channels, normalized (RMSNorm), then three H matrices are computed (pre, post, res): pre and post go through sigmoid to ensure non‑negativity, and res is projected by Sinkhorn. The final output is a composed combination of these components (formula illustrated by the paper’s figure). After multi‑layer composition, the signal flows stably without blowing up.
Why mHC isn’t slow: engineering optimizations
Theory alone is not enough; large‑model training must be fast. DeepSeek applies three engineering optimizations:
- Kernel fusion: custom GPU kernels via TileLang fuse matrix operations and normalization into single kernels to cut memory reads/writes. Activations use bfloat16 for speed, parameters stay in float32 for precision.
- Selective recomputing: memory is scarce, so not all intermediates are cached. Only every L_r layers is the main residual stored; others are recomputed on the fly to trade compute for memory. A block‑size formula balances memory and compute (L is total layers, n the expansion rate).
- DualPipe extension: in distributed training, a high‑priority stream overlaps communication with computation to reduce pipeline bubbles (idle time).
Results: with n=4, runtime overhead is only about 6.7% and memory increases by ~1.05x. Experiments on 3B–27B models show a loss reduction of ~0.021 and benchmark score improvements of 1–2%, with manageable overhead.
The deeper significance of mHC: a new architectural paradigm
mHC is more than a bugfix: it demonstrates that "constraints enable freedom." By restricting weights to a mathematical manifold, it unlocks richer architectures safely. The analogy is providing guardrails in a play area: bigger space, but safer. Going forward, large models may adopt manifold constraints to avoid uncontrolled scaling. DeepSeek’s paper is another example of open innovation that benefits teams with limited resources.
In short, mHC’s manifold guardrails solve HC’s runaway problem, making neural information flow steadier and more robust. This is not just a technical tweak but a sign of AI maturing from "wild growth" to "refined cultivation." If you work on AI training, mHC is worth trying.
▶️ Enjoyed this article? Creating great content takes effort!
Subscribe to our YouTube channel:
AI Rosetta
Your likes, subscriptions and shares mean the world to us! 🙏
For more AI news, visit:
https://www.airosetta.com