
On March 30, 2026 (Sunday), Alibaba's Tongyi Qianwen team officially released the next‑generation omnimodal large model Qwen3.5‑Omni (abbreviated Qwen3.5‑Omni). This marks another major upgrade in the Qwen series following Qwen3‑Omni in September 2025. Qwen3.5‑Omni achieves true "natively omnimodal" capabilities, seamlessly understanding and processing text, images, audio and audio‑video inputs, and supports real‑time voice‑dialogue output, making it one of the world's leading omnimodal large models.
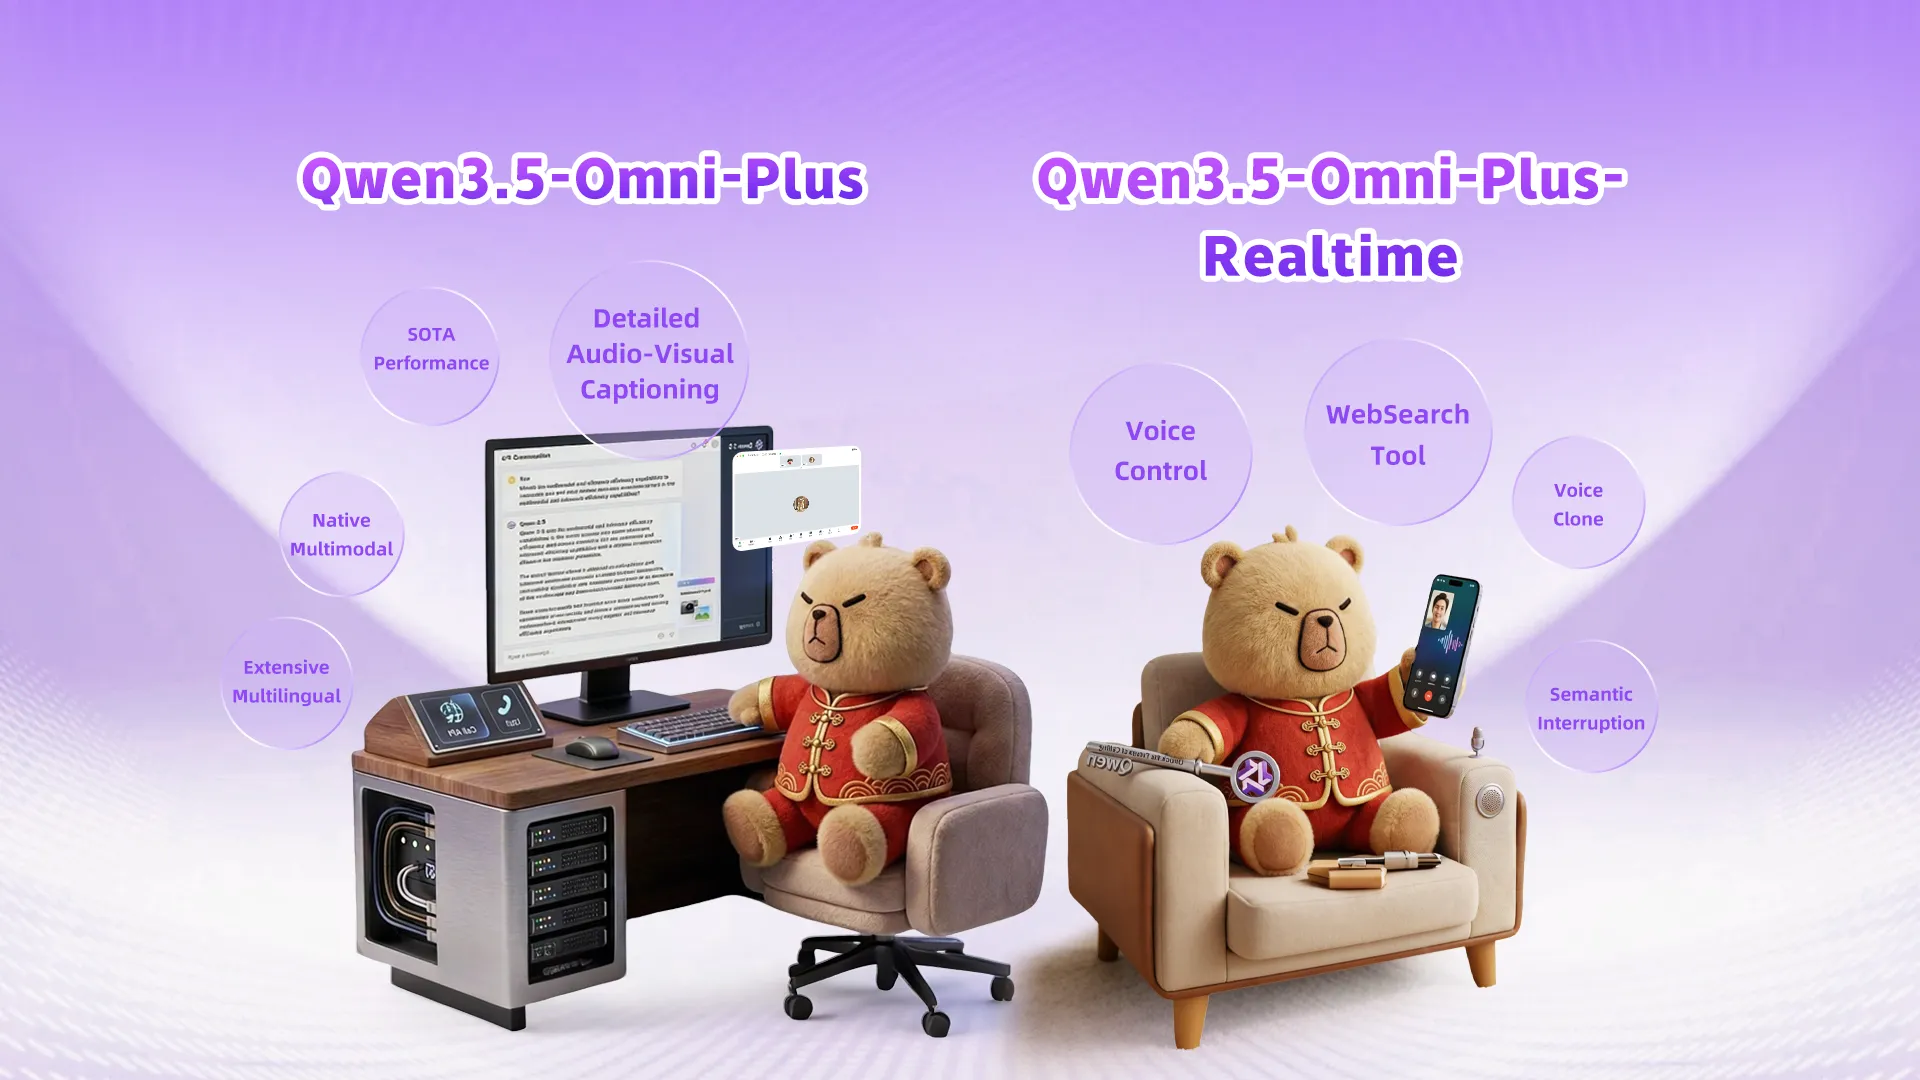
According to official data, Qwen3.5‑Omni achieved state‑of‑the‑art results across 215 audio‑video understanding, recognition and interaction tasks, with overall performance exceeding Google Gemini‑3.1 Pro, positioning it among the most powerful omnimodal models globally. The model is available through Alibaba Cloud ModelStudio (Bailian), offering Plus, Flash and Light Instruct API versions, with no open‑source plan at present.
Core innovations: Hybrid‑Attention MoE architecture + native multimodal pretraining
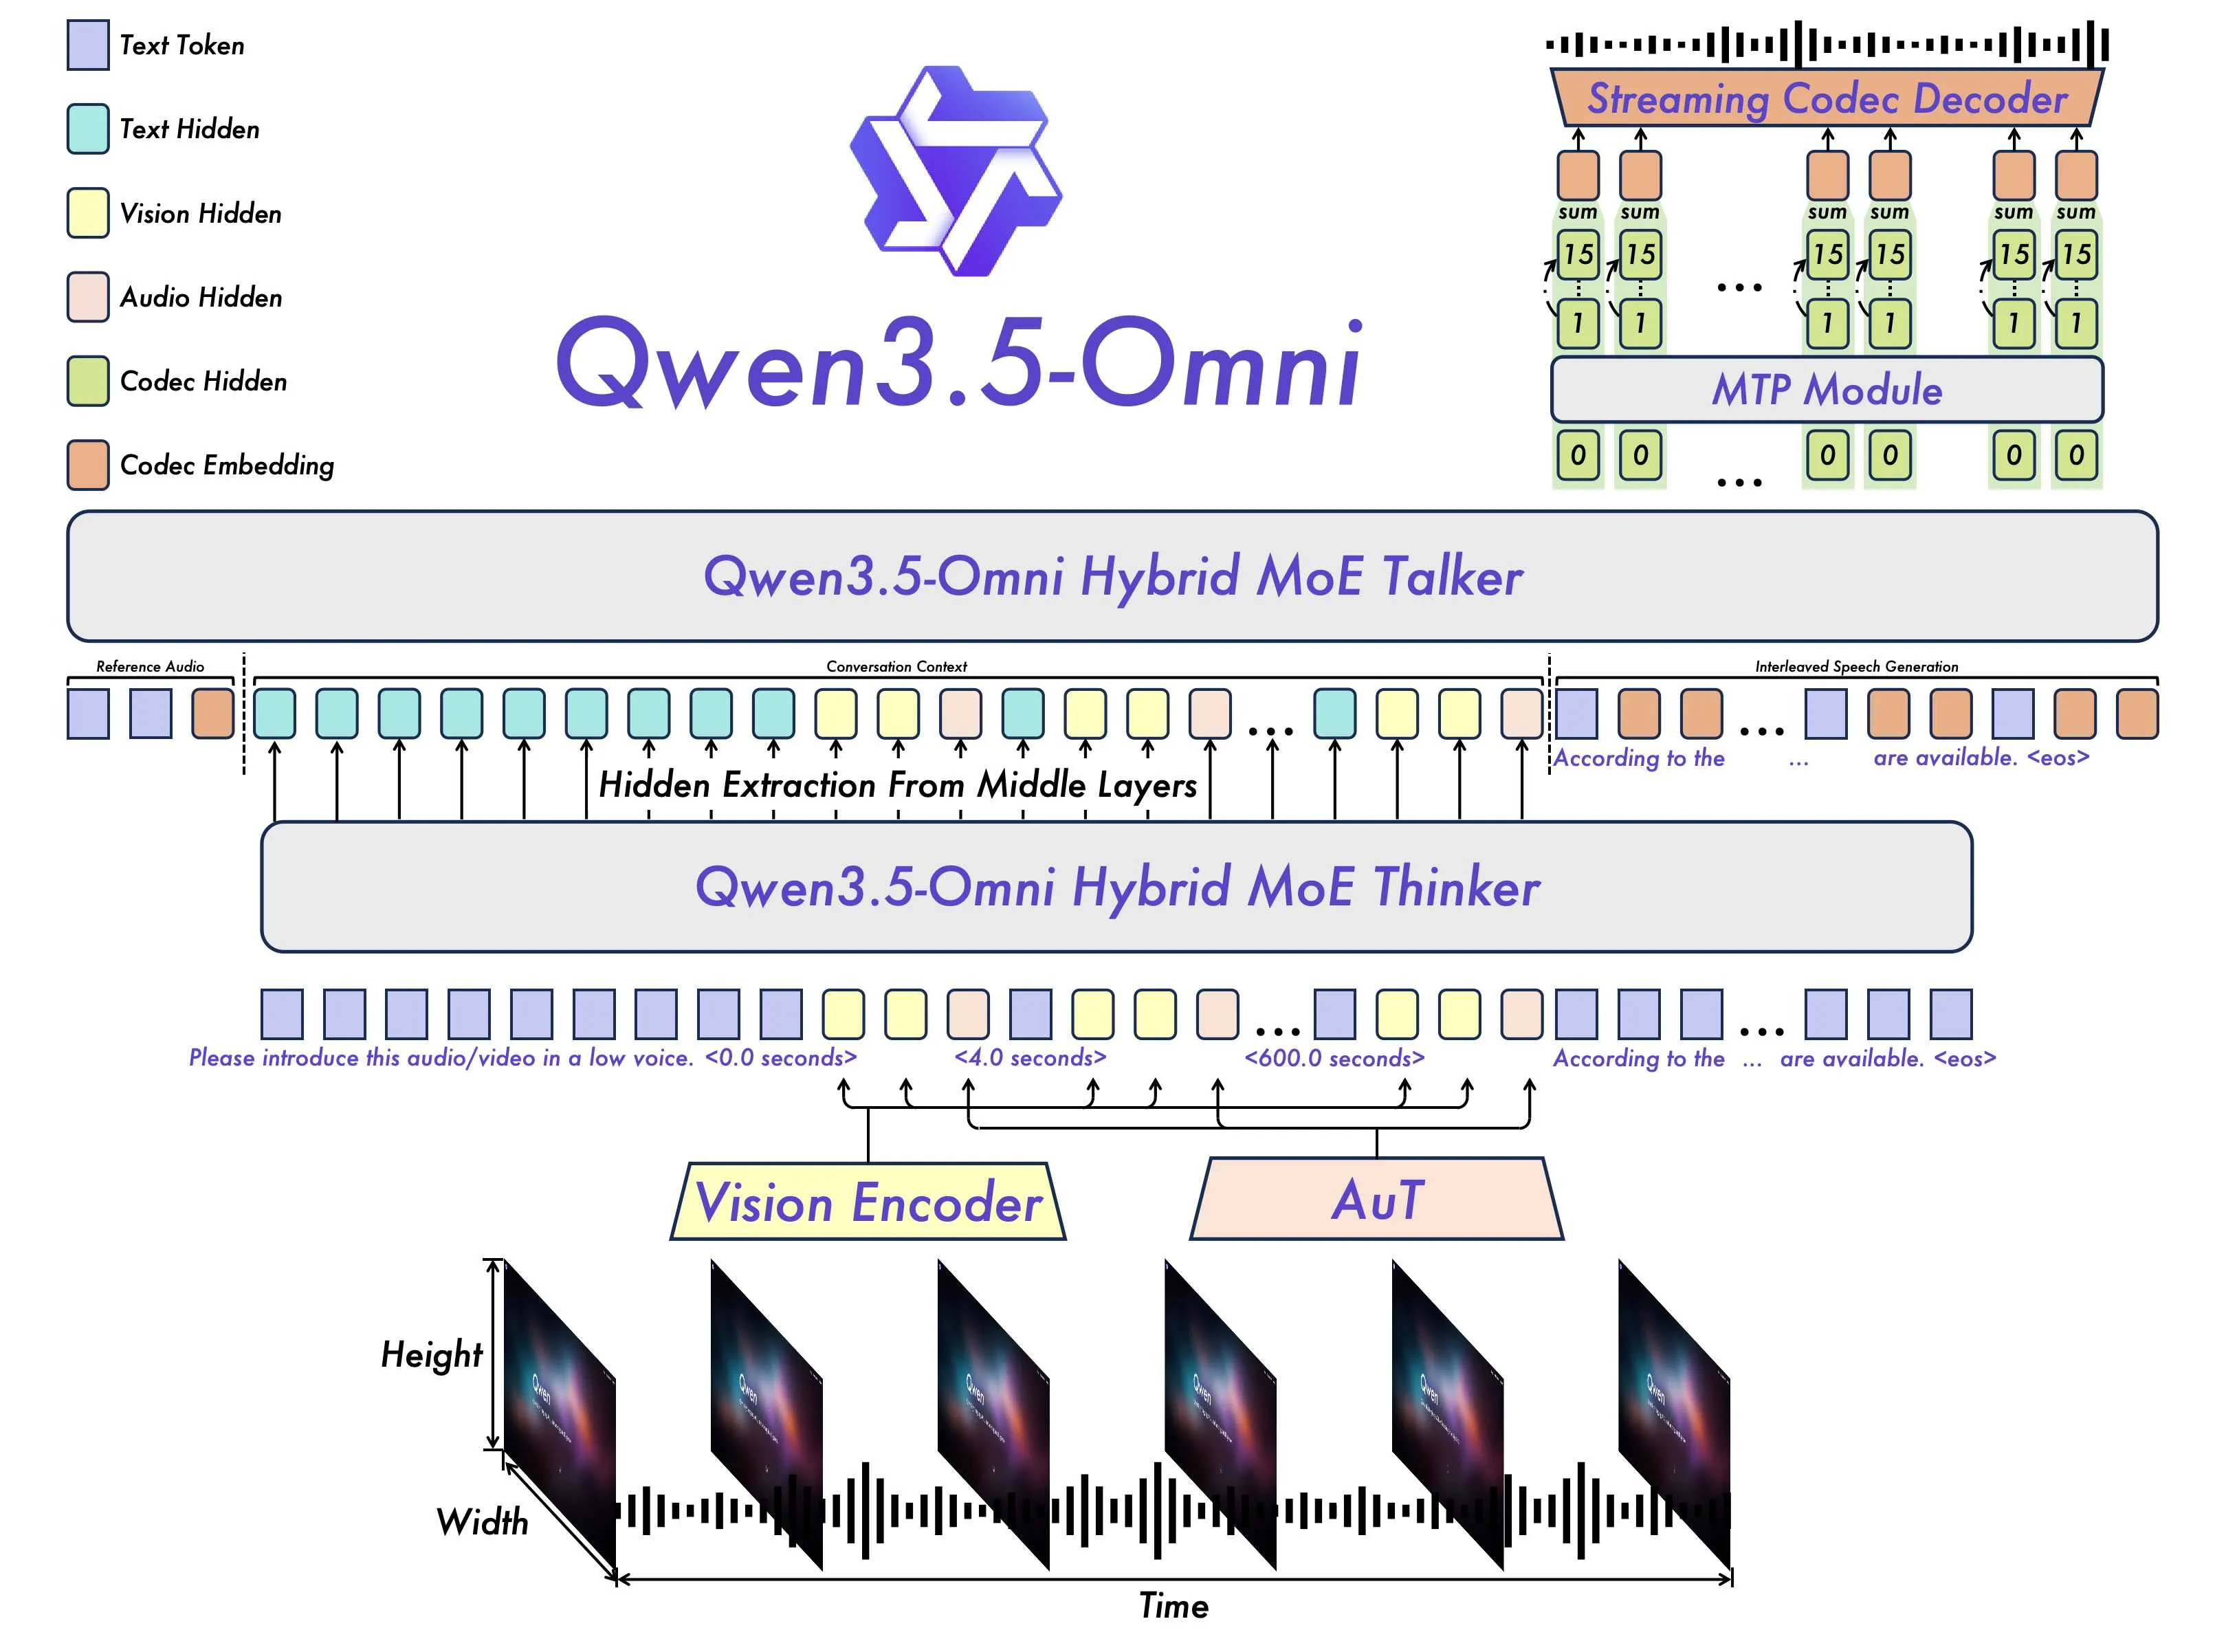
The most notable design of Qwen3.5‑Omni is that both the Thinker (reasoning module) and Talker (dialogue module) adopt a Hybrid‑Attention MoE architecture. This design combines linear attention (Gated Delta Networks) with sparse Mixture‑of‑Experts, retaining the high precision of traditional attention while greatly improving long‑sequence efficiency. Compared with the previous Qwen3‑Omni, Qwen3.5‑Omni implements an "early fusion" multimodal strategy, jointly pretraining massive text and visual data together with over 100 million hours of audio‑video data to avoid performance loss from later‑stage modality alignment.
Key capability breakthroughs include:
- Extreme long context and input limits: Supports a 256K long context, able to process in one pass over 10 hours of pure audio or over 400 seconds of 720p (1 FPS) audio‑video input, far exceeding most competitors.
- Multilingual and real‑time interaction: Speech recognition supports 113 languages and dialects, and speech synthesis supports 36 languages (a significant increase from the previous generation); new real‑time interaction features include semantic interruption, voice cloning and voice control, making conversational experience closer to human interaction.
- Structured audio‑video understanding: Can generate fine‑grained captions with timestamps and produce controllable structured descriptions (users can specify style, length and focus).
- Emergent abilities: Introduces "Audio‑Video Vibe Coding" — users can speak requirements to the camera and the model can autonomously generate complex code for apps, web pages and games, demonstrating strong embodied intelligence potential.
These innovations move Qwen3.5‑Omni from a "multimodal aggregation" approach toward a truly "natively omnimodal AGI," offering end‑to‑end solutions for short‑video/live‑streaming platforms, game development, and content creation for independent media.
Performance: multimodal SOTA and extreme cost optimization
Across 215 audio‑video benchmark tests, Qwen3.5‑Omni leads comprehensively, with key metrics in audio understanding and voice dialogue surpassing Gemini‑3.1 Pro. While maintaining high performance, inference efficiency is significantly improved: the Plus version's input cost per one million tokens is under 0.8 RMB, roughly one‑tenth of Gemini‑3.1 Pro, delivering a clear cost‑performance advantage.
Compared with Qwen3‑Omni, Qwen3.5‑Omni achieves leaps in long‑context handling, multilingual capabilities and audio‑video understanding, and adds real‑time interaction features. Versus international competitors, Qwen3.5‑Omni is more practical on "real‑world multimodal tasks," particularly for Chinese and multilingual scenarios.
Commercial deployment and ecosystem impact
The release of Qwen3.5‑Omni comes at a pivotal moment as global AI shifts from a "dialogue era" to an "agentic AI era." Alibaba Cloud ModelStudio has opened API access, enabling enterprises to quickly integrate the model into short‑video moderation, live‑captioning, game NPC dialogue, video content structuring and other scenarios. The Tongyi Qianwen app has also been updated to support real‑time voice/video interaction.
Industry impact:
- Accelerates China's independent innovation in omnimodal AI: In the US‑China AI competition, Qwen3.5‑Omni demonstrates a "punch‑above‑its‑weight" approach with low cost and high performance, offering affordable omnimodal capabilities to small and medium‑sized enterprises.
- Drives a multimodal application boom: Emergent abilities like Audio‑Video Vibe Coding could reshape thresholds in content creation, programming and education, spawning new interaction paradigms such as "video‑as‑prompt."
- Reshapes global competitive dynamics: International giants like Gemini and GPT face strong local challengers, likely accelerating multimodal iteration. At the same time, the Qwen series' dual open‑source plus API strategy offers more choices for global developers.
Challenges and outlook
Despite its strong performance, Qwen3.5‑Omni is not open‑sourced and is currently accessible only via API; whether the weights will be released in the future remains to be seen. In addition, compute consumption and real‑time optimization for omnimodal models will remain long‑term challenges.
The Tongyi Qianwen team says Qwen3.5‑Omni is an "important step toward natively omnimodal AGI." As more modalities are integrated and agent capabilities improve, the Qwen series is expected to further narrow the gap with top international models.
The release of Qwen3.5‑Omni reaffirms that Chinese AI has firmly entered the global leading tier in multimodal development. It not only provides practical tools for developers and enterprises but also injects "Eastern speed" and "cost advantages" into the global AI ecosystem. In the wave toward general artificial intelligence, Qwen3.5‑Omni is writing a new chapter for Chinese AI with its omnimodal capabilities.
▶️ Enjoy this article? Creating content is hard work!
Follow our YouTube channel:
AI Rosetta
Your likes, subscriptions and shares are our greatest support! 🙏
More AI news at: https://www.airosetta.com