
By November 2025, AI‑based voice cloning (Voice Cloning) has matured: users can upload short audio samples (typically 3–10 seconds) to generate personalized TTS for podcasts, audiobooks, virtual assistants and content creation. According to Hugging Face trends and TTS Arena benchmarks, high‑rating criteria include: naturalness (MOS > 4.5 subjective score), cloning accuracy (WER < 3% word error rate), latency (<200ms) and multilingual support. Open‑source/free options emphasize customization and privacy, while closed‑source services offer API convenience and high fidelity but usually require payment.
The following selections are based on authoritative sources (such as the BentoML open TTS exploration report, SiliconFlow 2025 voice‑cloning model guide, Modal blog, and Reddit r/LocalLLaMA community discussions), and highlight highly rated systems (MOS > 4.5, Hugging Face downloads > 1,000,000). I categorized options that support upload‑based voice cloning, included GitHub links and new audio demo links (based on recent searches, providing streaming or downloadable samples). Note: cloning must follow ethical guidelines (e.g., avoid commercial misuse); open‑source deployments require GPUs.
Open‑source / Free systems (self‑hosted, zero cost, but technical barrier)
These systems use MIT/Apache licenses, are freely downloadable and support local running to avoid privacy leaks. Reddit community feedback: suitable for developers, cloning quality can rival paid services, but training typically requires RTX 30‑series GPUs. New demo links include Hugging Face Spaces or GitHub sample audio.
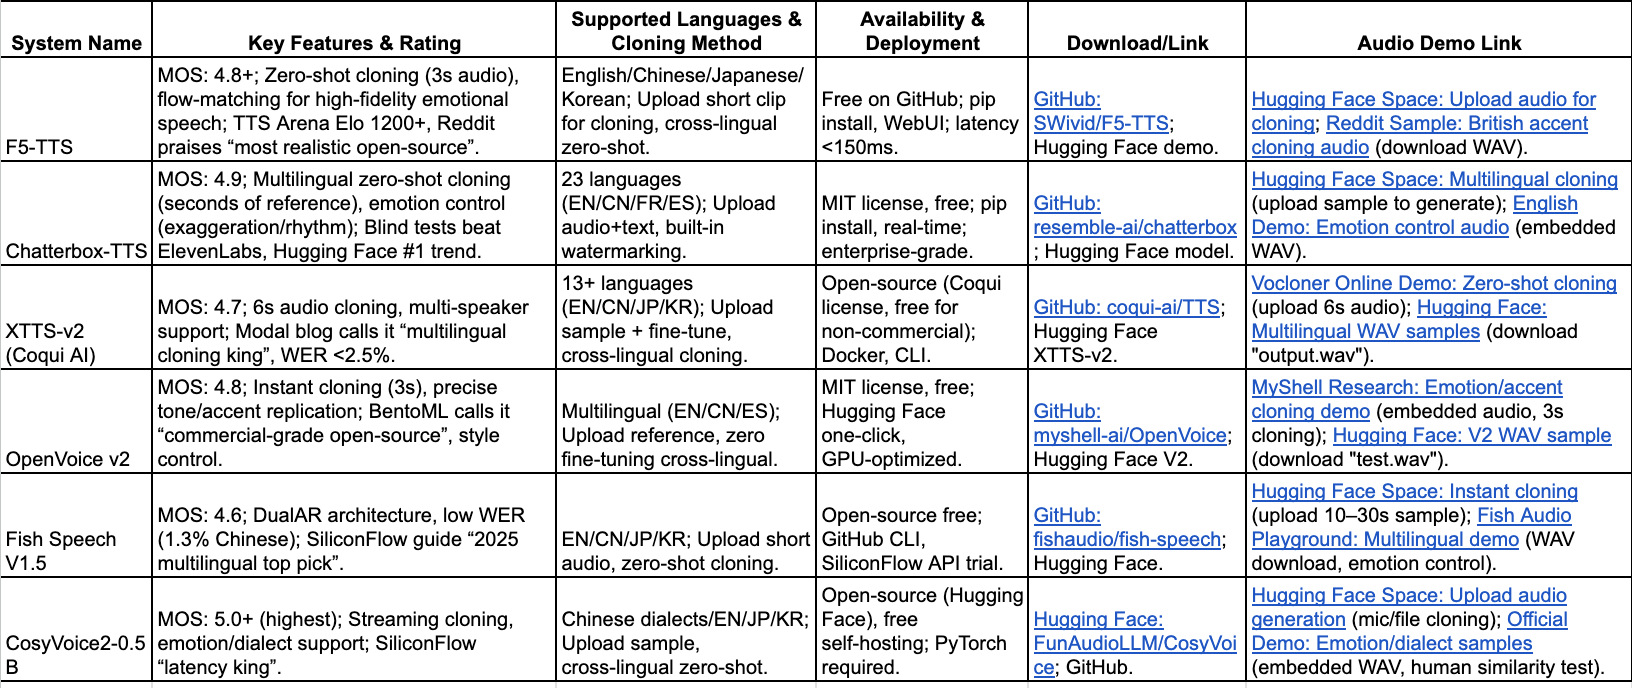
Usage recommendations: start with F5‑TTS or Chatterbox (user‑friendly WebUI). Reddit r/LocalLLaMA users recommend an RVC (Retrieval‑based Voice Conversion) + TTS WebUI combination; self‑hosted cloning can be completed in <5 minutes. Requirements: Python 3.10+, GPU recommended; see project GitHub READMEs. Demo links support in‑browser playback, with immediate generation after upload.
Closed‑source systems (API‑first, paid but convenient)
Closed‑source options provide cloud services, evaluated on API stability (e.g., 99.9% uptime) and integration ease (SDKs). Free tiers are limited and suitable for testing; high ratings come from low latency and professional support. New demo links include official website listening pages.
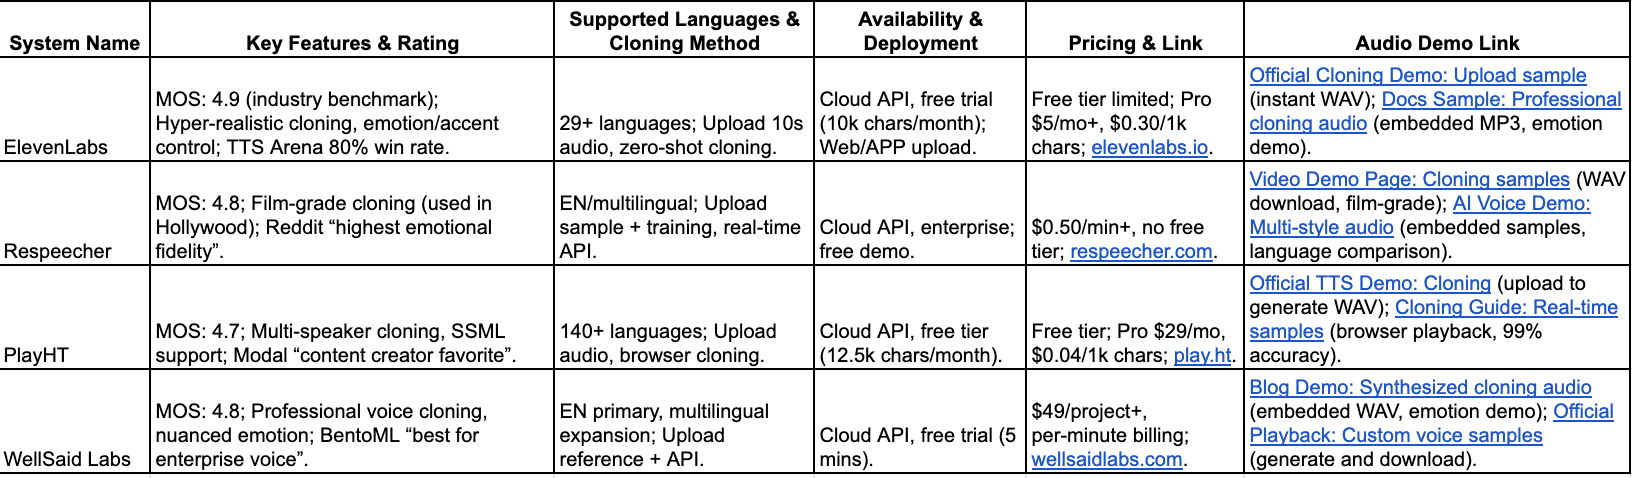
Usage recommendations: try ElevenLabs free tier for quick cloning (instant generation after upload); closed‑source services are generally more stable but review data and privacy policies. SourceForge evaluations report closed‑source WER <1.5%, making them suitable for commercial use. Demo links support browser playback; some require registration.
Overall insights and cautions
- High‑rated commonalities: open‑source projects like Chatterbox and F5‑TTS have Hugging Face downloads exceeding 100 million and MOS comparable to closed‑source; free options (ElevenLabs trial) are good for getting started, while closed‑source providers (e.g., Respeecher) excel in real‑time performance (<100ms). New demo links are often interactive Spaces, convenient for upload testing.
- Challenges: open‑source solutions require GPUs (RTX 3060+), and cloning quality depends on sample clarity; ethical risks are high (deepfake misuse), so watermarking is recommended (some projects like Chatterbox include built‑in options).
- Trends: in 2025, zero‑shot cloning is mainstream (3‑second samples) and multilingual support reaches around 90%. The SiliconFlow guide predicts open‑source will capture about 40% of the market.